multifariousICU Support for Trados Studio
Description
Text that includes a number is written differently from one language to the next. English has “1 file” and “2 files”. Russian needs a different ending for 2, for 5 and for 21. Arabic has six forms. Japanese has one. Application developers handle this with ICU MessageFormat, a notation in which one string carries every form the source language needs:
{count, plural, one {# unread message} other {# unread messages}}
ICU is the International Components for Unicode, the library most applications use to format text for a language. MessageFormat is its notation for text that changes with a number or a choice. The application picks the right form at run time using the plural rules for the user’s language from CLDR, the Common Locale Data Repository, which is the Unicode Consortium’s database of language rules.
For a translator this notation is hard work. The whole expression arrives as one segment. The translator has to know the syntax, know which forms the target language needs and which numbers select them, and type the missing forms by hand without breaking a brace.
multifariousICU Support for Trados Studio does that work for them. Each form becomes its own segment, a complete sentence, with the syntax protected. The plugin uses the same CLDR data as the application, so the forms it offers are the forms the application will use. Note: if the translation is wrong please let me know and I will correct it, but for now try to focus on the message we’re trying to explain:
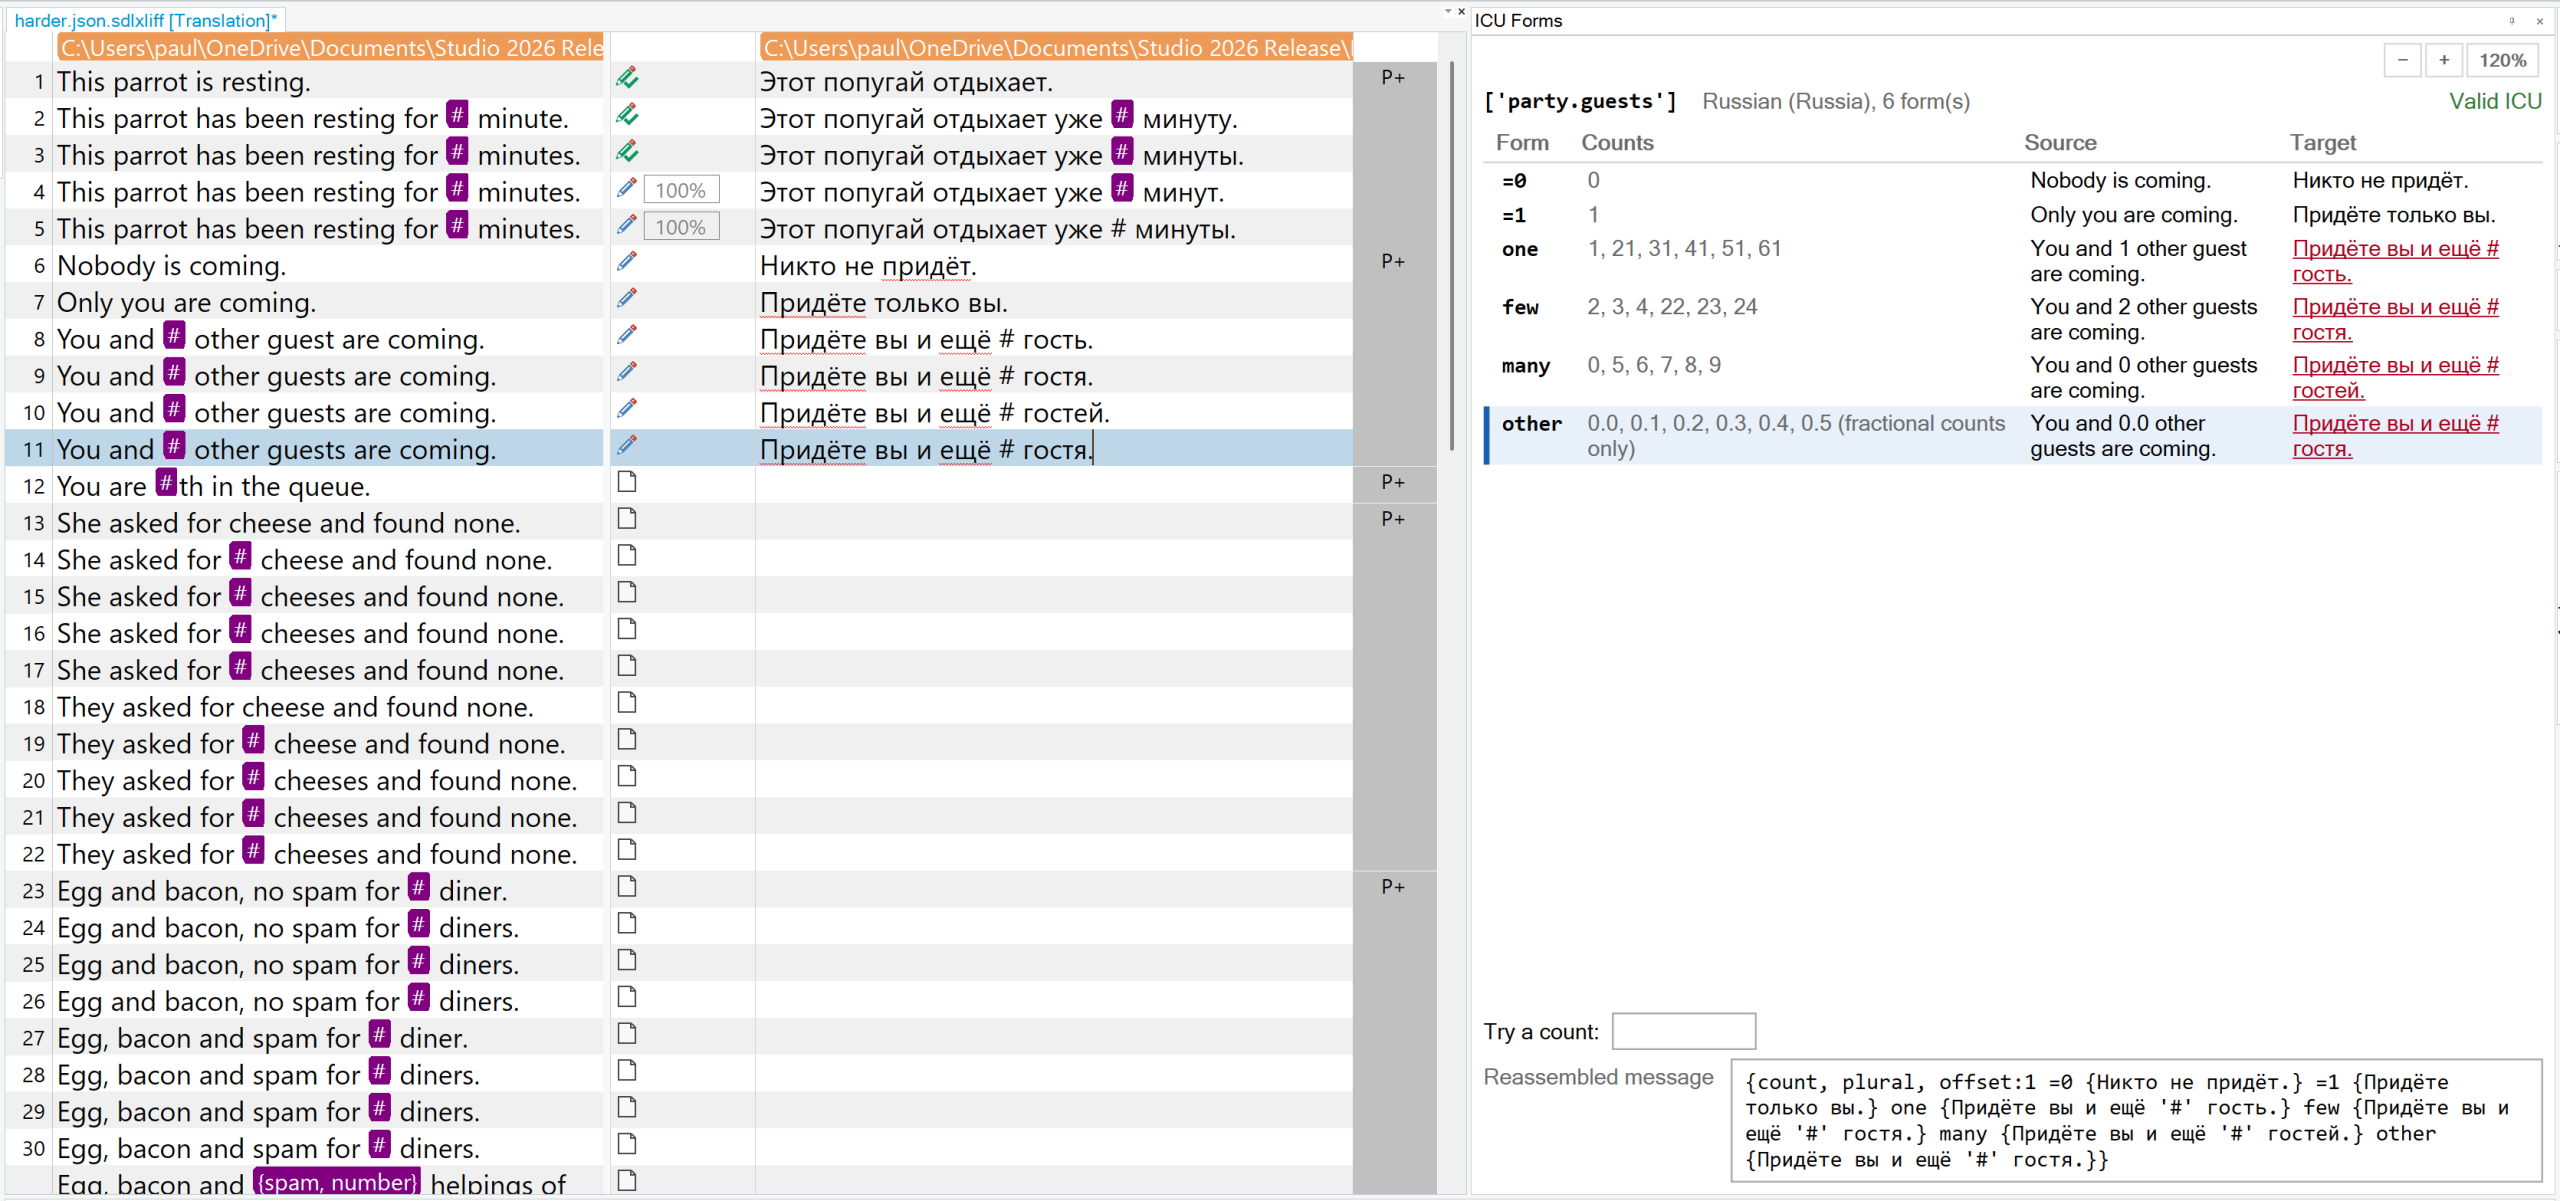
The editor with a message expanded for Russian, four segments with their placeholder tags, and the ICU Forms window below. Also note the red text indicating I still haven’t used a proper tag in the target.
What an ICU message contains
A message is text with arguments in braces. A plain argument such as {name} is replaced by a value. A plural argument chooses one of several branches by a number:
Hello {name}, you have {count, plural, one {# unread message} other {# unread messages}}!
Inside a branch, # stands for the number. The branch names are the plural categories defined by CLDR: zero, one, two, few, many and other. Each language uses some of them, and CLDR says which numbers select each:
| Language | Plural forms | The form for 5 |
|---|---|---|
| English | one, other | other |
| Russian | one, few, many, other | many |
| Arabic | zero, one, two, few, many, other | few |
| Spanish | one, many, other | other |
| Japanese | other | other |
many
Three other constructs appear in real files:
-
Exact values such as
=0 {No messages}match one number only and take precedence over the categories. -
Ordinals (
selectordinal) work like plurals but for “1st”, “2nd”, “3rd”. -
Selects choose a branch by a value rather than a number, usually gender:
{gender, select, female {...} male {...} other {...}}. The branches are decided by the developer and are the same in every language.
Two rules of the notation matter to a translator. A literal apostrophe is written as two, It''s, and a literal brace is wrapped in apostrophes, '{'. The plugin takes care of both.
What the plugin does
ICU Expand Plural Forms is a batch task. For every plural and ordinal message in a file it works out which forms the target language needs and lays the message out as one segment per form. Each segment is the whole sentence with that form in place, so “Hello {name}, you have # unread messages!” is one segment for Russian “few”, not a fragment. The syntax between the segments is locked. Inside a segment, {name} and # are placeholder tags, which you place like any other tag in Studio.
ICU Finalise Messages is the batch task for the end of the workflow. It removes the forms the language does not use, escapes apostrophes and braces typed as text, checks that every placeholder in the source is in the target, fills an untranslated form from the source with a warning, and turns the placeholder tags into locked text, which is the shape Studio’s file writers need. Run it before Generate Target Translations.
ICU Forms is a window under the editor that shows every form of the message the active segment belongs to, with the numbers that select each form, the source and target as sentences, and the message reassembled as you type.
ICU Verifier works like Studio’s tag verifier and reports what is still wrong with a message.
Installation
-
In Trados Studio, open the integrated AppStore, or download the
.sdlpluginfrom the plugin’s AppStore record at https://appstore.rws.com/plugin/490 and double-click it. -
Search for multifariousICU Support for Trados Studio and install.
-
Restart Studio.
You will then find:
-
ICU Expand Plural Forms and ICU Finalise Messages in the Batch Tasks list and in task sequences.
-
ICU Forms on the editor’s Add-ins tab, in the multifarious ICU group.
-
ICU Verifier under Project Settings, Verification.
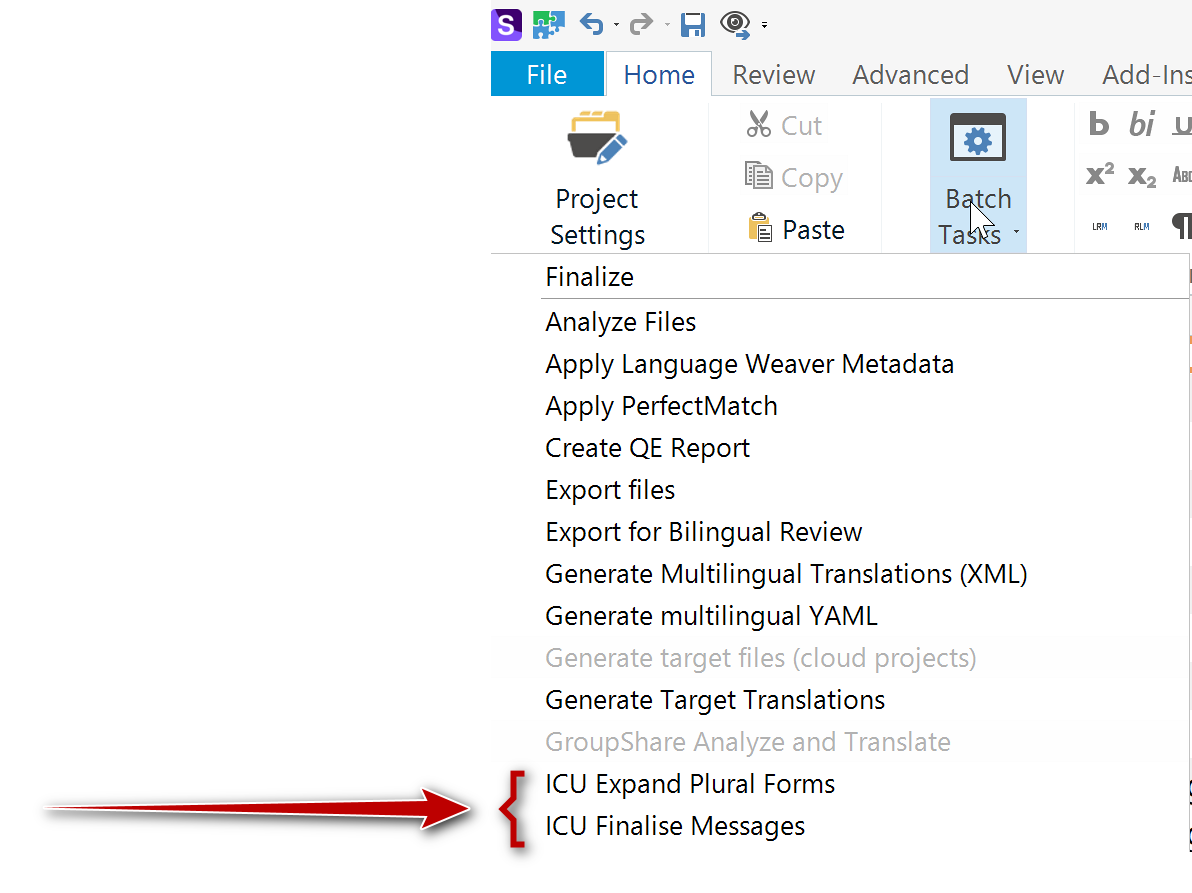
The Batch Tasks drop-down with the two ICU tasks.
Requirements: Trados Studio 2026 on Windows. The ICU parser and the CLDR data are inside the plugin.
Which files
The tasks work on Studio’s JSON and Java Resources file types. Other files in a project are left alone, and the ICU Forms window says so when you open one.
A value is expanded when it contains a plural or ordinal message. A value with arguments but no plural, such as “Hello {name}, welcome back!”, becomes one segment with the arguments protected. A value with no braces is not touched. A value with braces that is not valid ICU is left as it is, with a warning in the report.
Your first project
Take a JSON file with a message like this:
"inbox.unreadCount": "Hello {name}, you have {count, plural, one {# unread message} other {# unread messages}}!"
-
Create a project from it into Russian, Arabic and Japanese, with the default task sequence.
-
Run ICU Expand Plural Forms on all target files: select the files, Batch Tasks, ICU Expand Plural Forms, Next, Next, Finish. Leave the settings at their defaults.
-
Open the Russian file in the editor.
The message is now four segments, one per Russian form:
| Form | Source segment | Selected by |
|---|---|---|
| one | Hello {name}, you have # unread message! | 1, 21, 31, 41, 51, 61 |
| few | Hello {name}, you have # unread messages! | 2, 3, 4, 22, 23, 24 |
| many | Hello {name}, you have # unread messages! | 0, 5, 6, 7, 8, 9 |
| other | Hello {name}, you have # unread messages! | fractions such as 0.5 |
Click ICU Forms on the Add-ins tab. The window lists the four forms with the numbers that select each. The tooltip on a row adds where its source text came from, “other” for few and many because English has no such forms, and a grammar hint where one is known, such as the genitive plural for many.
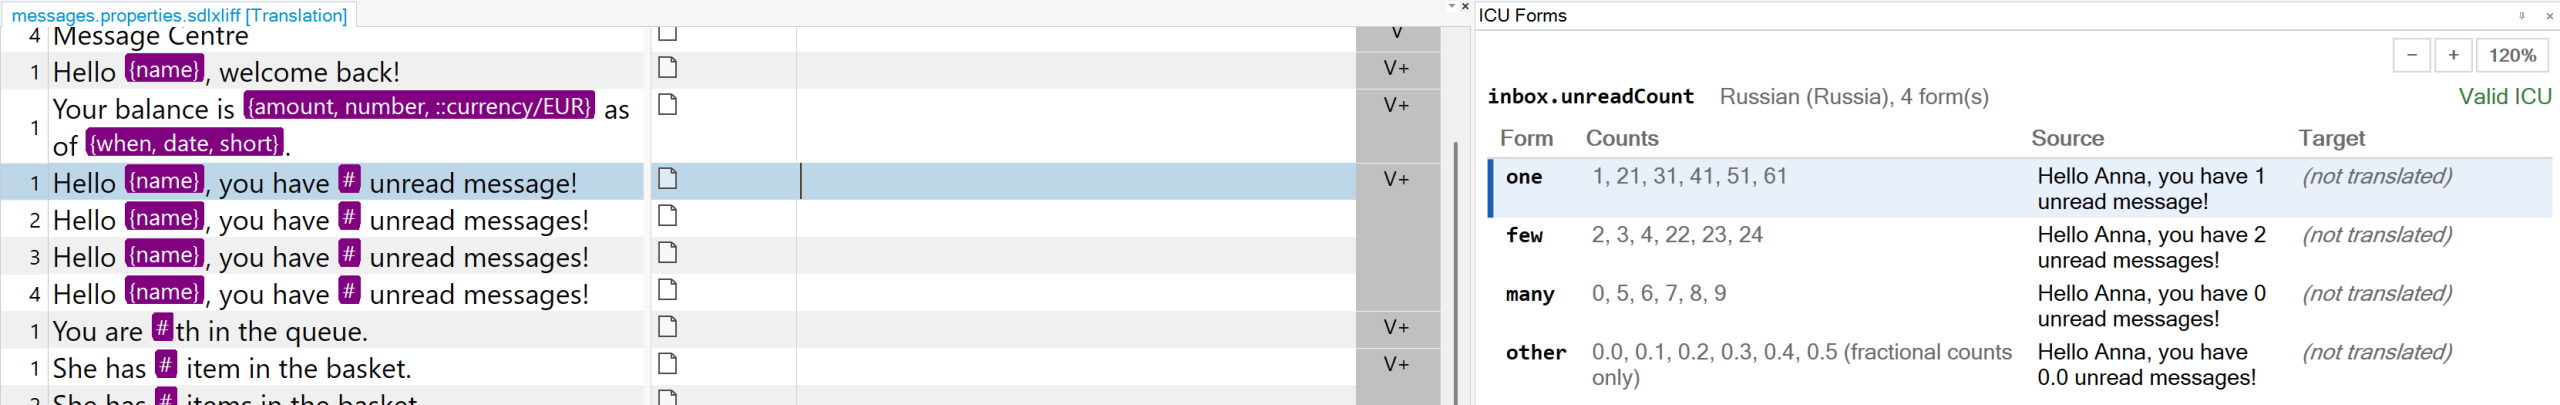
The four Russian segments and the ICU Forms window.
Open the Arabic file and the same message is six segments. Japanese has one. Each language gets its own forms because the task runs on each language’s own file.
Where in the workflow
Expand runs on the target files, so it must come after Copy to Target Languages. Put it before Analyse Files and Pre-translate, so word counts and translation memory matches see whole sentences. Either run it as a batch task straight after the project is created, or add it to a custom task sequence after Copy to Target Languages (if you are running the Professional version of Trados Studio, otherwise you need to run these tasks after the project has been created, or simply as separate actions and not part of a custom task).
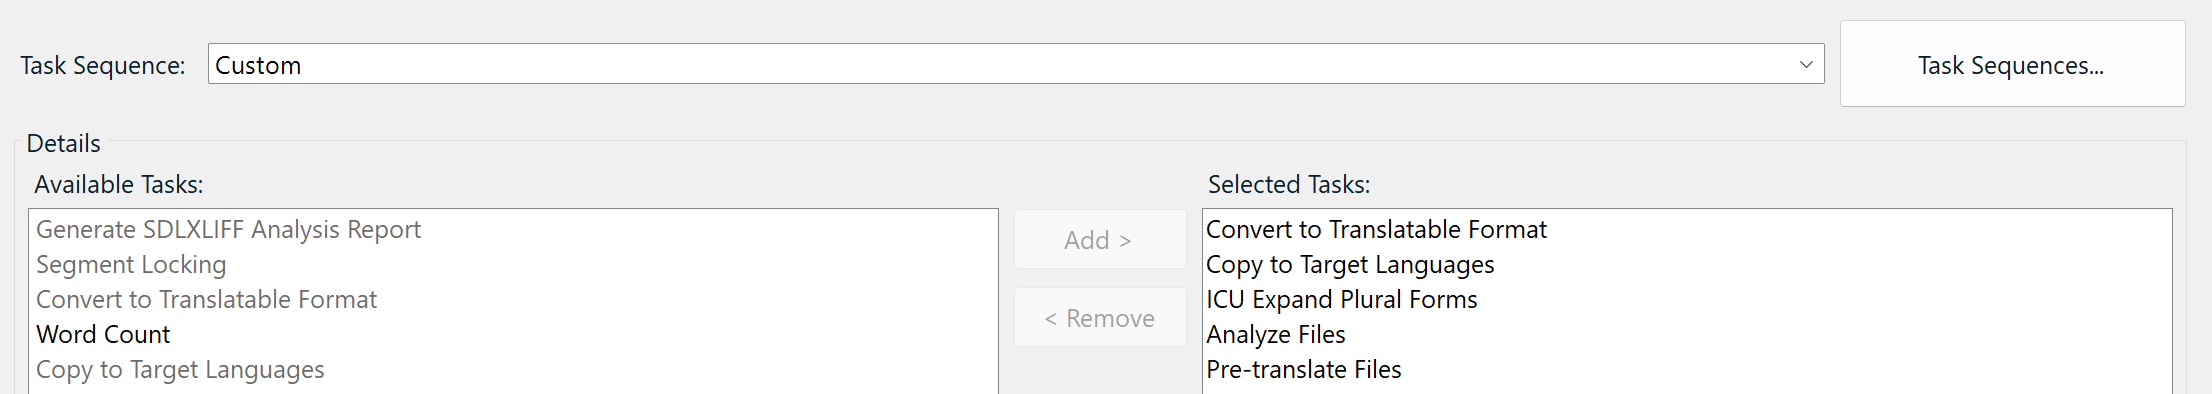
A task sequence with Expand after Copy to Target Languages and Finalise after Update Main Translation Memories.
Translating
Each form is an ordinary segment. Translate the sentence as your language needs it for the numbers shown in the ICU Forms window. Word order and agreement can differ from one form to the next.
-
Placeholders are the arguments and the count marker:
{name},{amount, number, ::currency/EUR},#. They are tags. Place them where your language needs them with QuickPlace (Ctrl+comma), Ctrl+Alt+Down, or by copying the source. If one is missing from a target, the ICU Verifier and Studio’s tag verifier report it. The expand settings can lock them so they cannot be moved or deleted; locked tags are not offered by QuickPlace. -
Locked text between segments is the message’s syntax. Leave it alone.
-
Apostrophes and braces are typed as in any text. Finalise turns
It'sintoIt''sand a literal{into'{'in the generated file. Studio’s AutoCorrect may replace a straight apostrophe with a typographic one, which ICU treats as ordinary text. -
A
#typed as text is shown literally in the application. Use the#tag from the source instead.
The ICU Forms window
Click ICU Forms on the Add-ins tab. The window docks under the editor and follows the active segment.
-
The header names the message key, the target language and the number of forms, and shows whether the reassembled message is valid ICU.
-
many -
Try a count: type a number and the row it selects is highlighted. Exact values match first, then the language’s rules, as in the application.
-
Reassembled message: the whole target message as Finalise will write it, updated as you type, with “Valid ICU” or the parser’s message beside it.
-
Zoom: Ctrl and the mouse wheel, or the buttons in the top right corner, from 60% to 250%. The zoom is remembered.
For a select containing a plural, such as a gendered message, the Form column shows the full path: “female / one”, “female / few”.
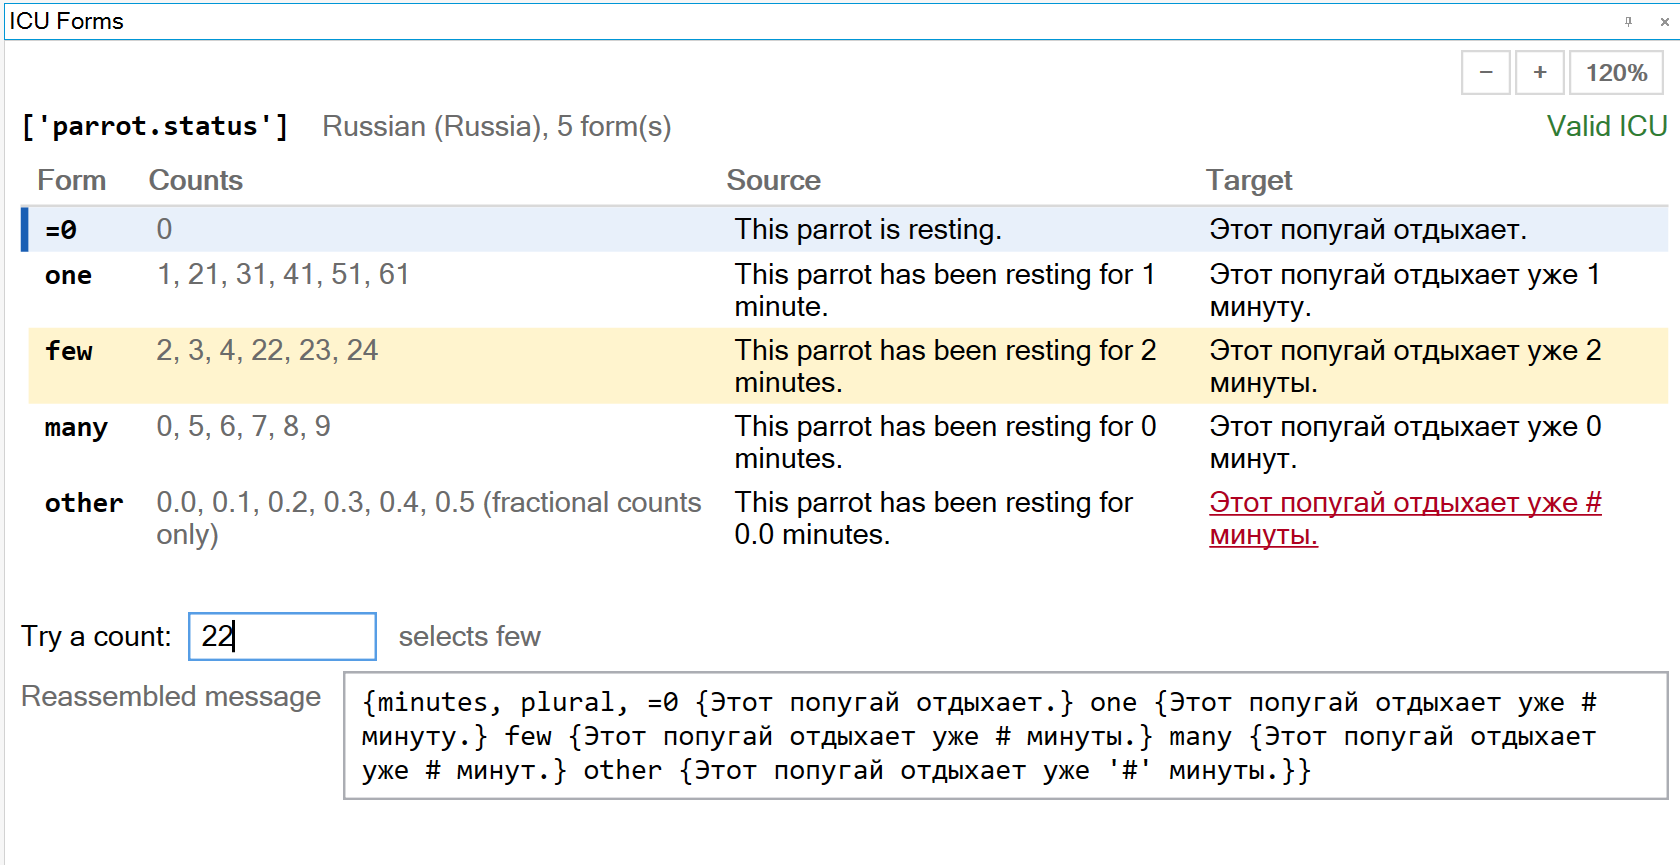
The window with 22 typed in the count box and the few row highlighted.
When there is nothing to show, the window explains why: the segment is ordinary text, the file has not been expanded, the file type is not supported, or no document is open.
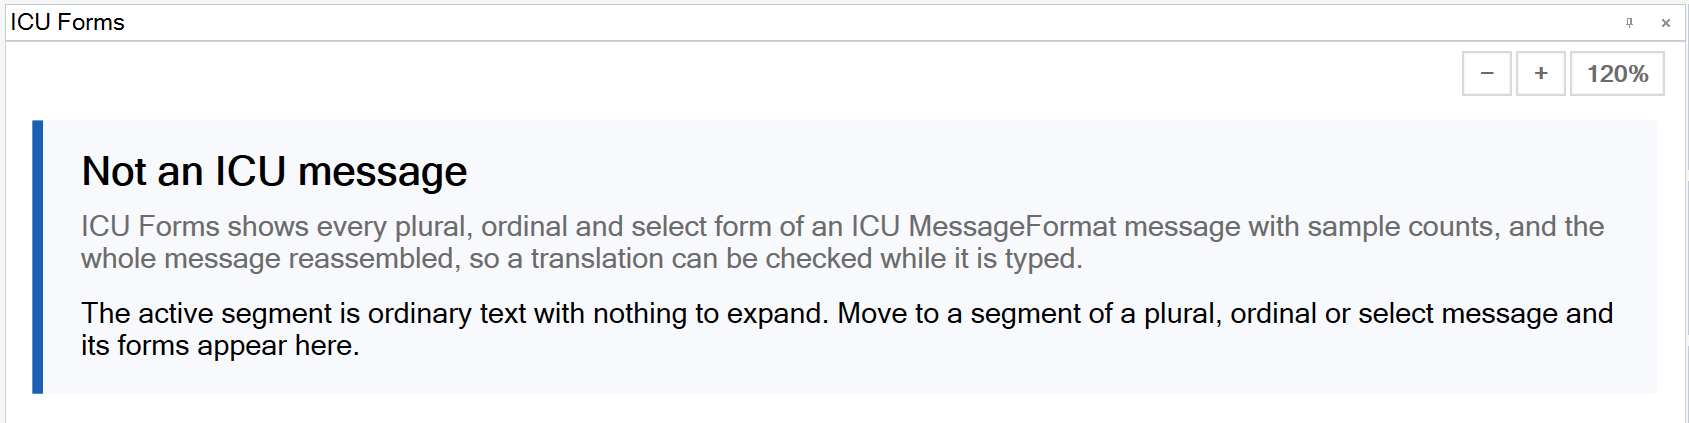
The panel shown for an ordinary segment.
The verifier
Press F8 or confirm a segment and the ICU Verifier reports in the Messages window beside Studio’s own verifiers:
| Finding | Default severity | Meaning |
|---|---|---|
| The form “count:few” has no translation | Warning | Every form the language needs must be translated. Finalise uses the source text if you leave it. |
| The protected placeholders differ from the source | Error | A placeholder tag is missing from the target or one has been added. Studio’s tag verifier reports this too. |
| A ‘#’ typed as text will be shown literally | Warning | Use the count marker tag. |
| The reassembled message is not valid ICU | Error | The message names the position of the problem. |
Under Project Settings (or Options), Verification, ICU Verifier you can switch the verifier off and set the severity of each check.
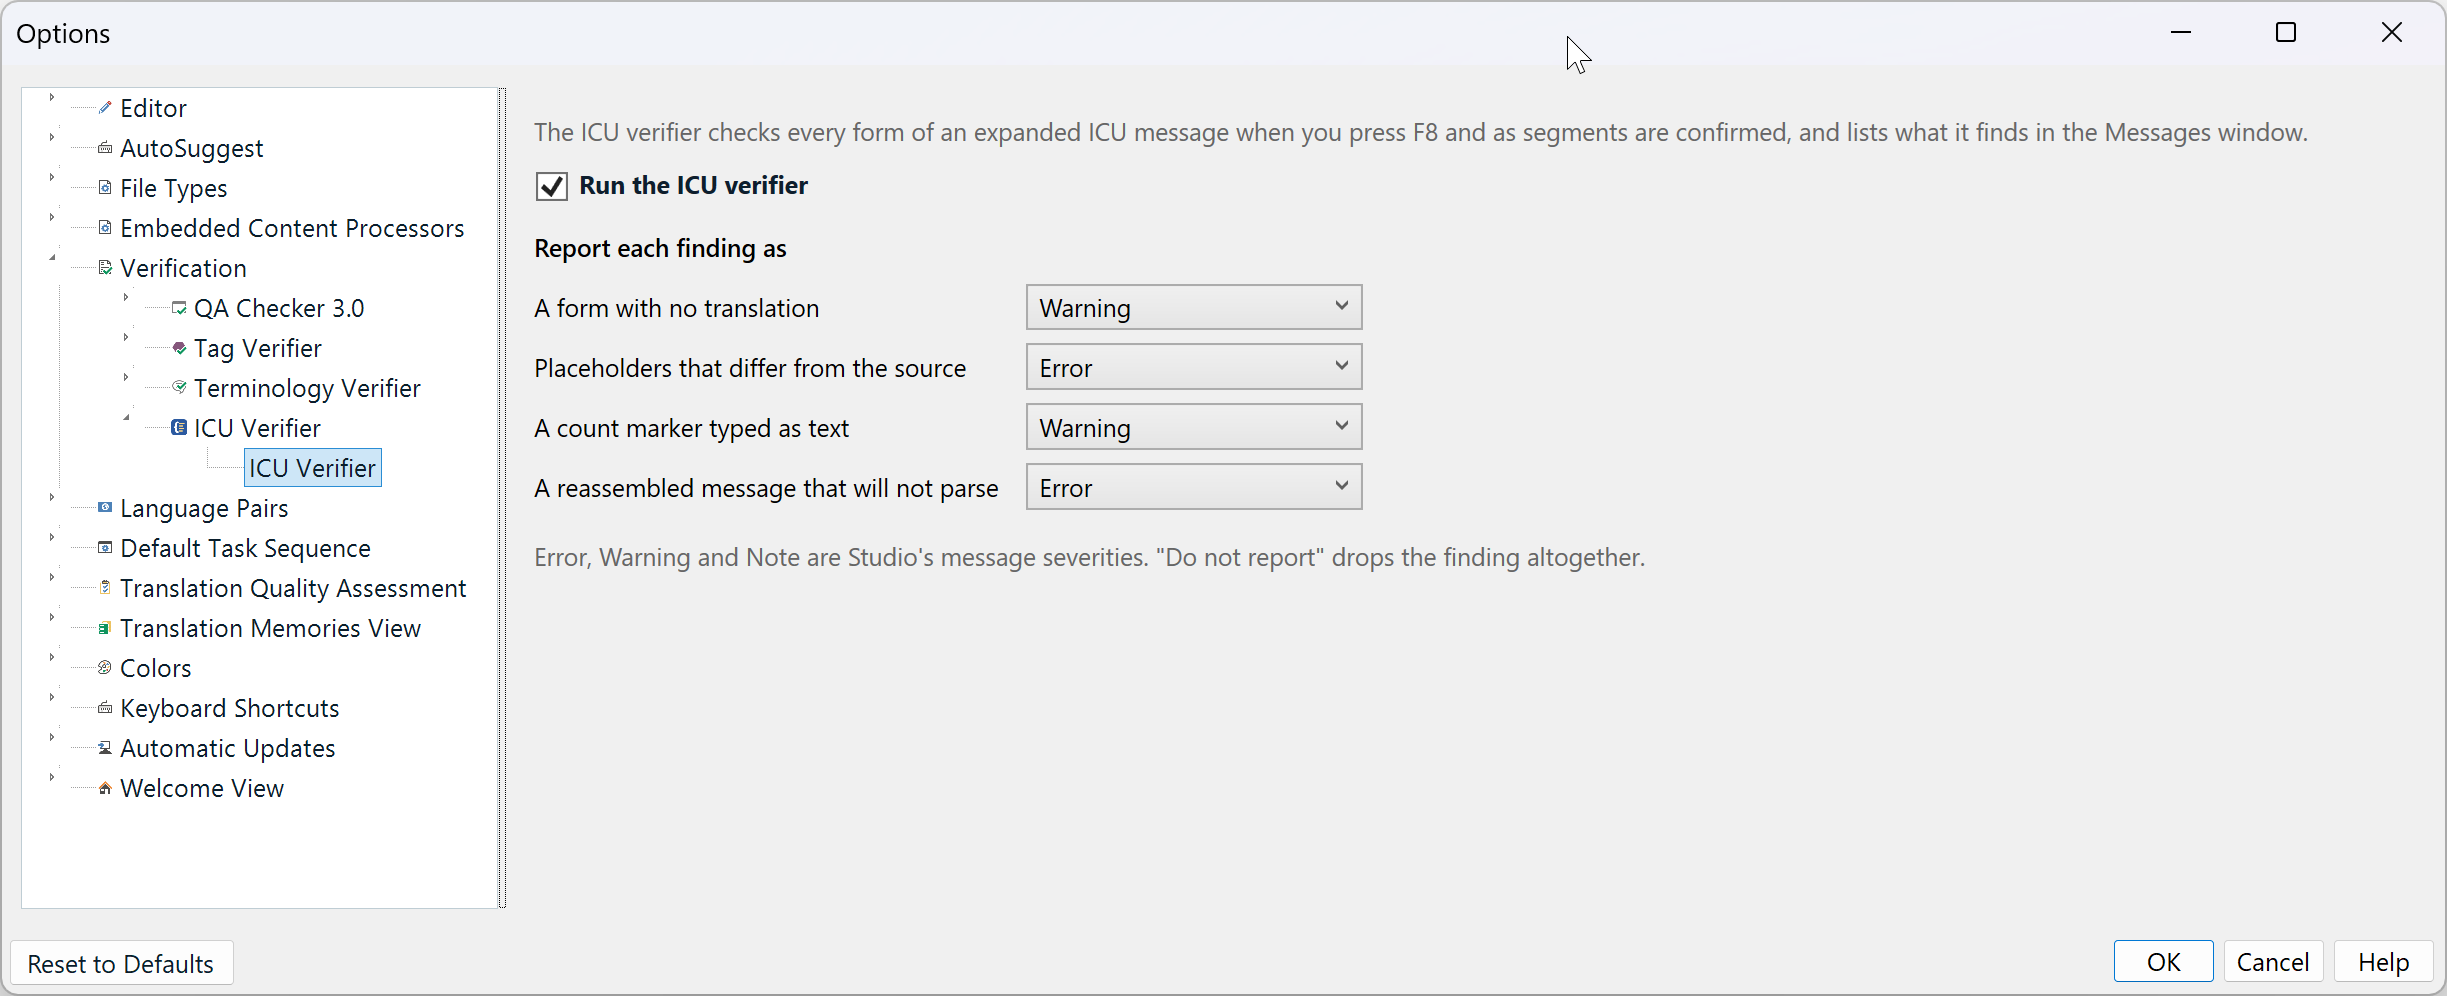
The verifier settings page.
The settings
The pages appear on the Settings step of the batch task wizard, under Project Settings, and in project templates. Each group has a help panel.
The expand settings page.
Messages to expand
Plural and ordinal messages, both on by default. A message that contains neither is left as it is. Selects are never expanded, because their branches are decided by the developer. Each branch of a select still becomes its own sentence, and a plural inside a select is expanded as usual.
Source text for forms the source language does not have
English has “one” and “other”. A Russian “few” segment has to start from one of them, and that text is what the translator sees as the source. The default takes the source form with the same name where there is one, otherwise “other”. The alternative takes “other” for every form. Some teams prefer that because the English “one” form is often written for exactly one item.
Placeholders
Whether the placeholder tags are locked, off by default. Unlocked, a tag can be placed with QuickPlace or Ctrl+Alt+Down, and a missing one is reported by the verifiers. Locked, a tag cannot be moved or deleted, but it is not offered by QuickPlace, so a form typed from scratch has to start from a copy of the source.
Branch budget
A message with two independent plurals multiplies: six forms times six is 36 segments for Arabic. The budget, 24 by default, caps that. Over the budget, the message keeps the source’s own branches with the syntax protected, and the report says so. Raise the budget if you want every form, or ask the developer to split the message, which may be the better fix.
When a value does not parse as an ICU message
A brace without its partner, an apostrophe where ICU reads it as a quote, a misspelt keyword. Leaving the value as it is with a warning keeps the rest of the file moving. Stopping the task is for a pipeline where a broken message must not reach a translator.
Finalise: when a form has no translation
Use the source text and warn, the default, keeps the generated file valid and records the gap in the report. Stop the task is for a delivery where an untranslated form must not slip through.
Finalise: when the placeholders differ
Warn and continue, the default, leaves that message with its placeholders as tags so it can be corrected, and the report says it must be finalised again before generating. Stop the task stops at the first mismatch and changes nothing.
The finalise settings page.
Finalising and generating the target files
-
Run ICU Finalise Messages on all target files after the translation memories have been updated.
-
Check the report, one per language pair in the Reports view. It lists every message, the forms removed, the segments filled from the source, and every warning.
-
Run Generate Target Translations. Each message comes back with exactly the forms the language needs, exact values kept, and apostrophes and braces escaped.
A finalise report in the Reports view.
Finalise can be run again after further editing. A second run on a clean file changes nothing.
What the generated file looks like
Source:
"inbox.unreadCount": "Hello {name}, you have {count, plural, one {# unread message} other {# unread messages}}!"
Russian target:
"inbox.unreadCount": "{count, plural, one {Привет, {name}, у вас # непрочитанное сообщение!} few {Привет, {name}, у вас # непрочитанных сообщения!} many {Привет, {name}, у вас # непрочитанных сообщений!} other {Привет, {name}, у вас # непрочитанного сообщения!}}"
The text that stood outside the plural in the source is inside every branch in the target. That is the recommended way to write translatable ICU, because each form is a whole sentence and word order is free. The arguments are unchanged.
Harder messages
The counts below are what the expand task produces from an English source with the default settings.
An exact value with a plural. =0 matches that number only and is always its own segment.
{minutes, plural, =0 {This parrot is resting.} one {This parrot has been resting for # minute.} other {This parrot has been resting for # minutes.}}
| Target | Segments | Forms |
|---|---|---|
| German | 3 | =0, one, other |
| Russian | 5 | =0, one, few, many, other |
| Arabic | 7 | =0, zero, one, two, few, many, other |
| Japanese | 2 | =0, other |
An offset. With offset:1 the count marker shows the number minus one, and =0 and =1 still match the real number. The ICU Forms window shows the numbers each form is used for.
{count, plural, offset:1 =0 {Nobody is coming} =1 {Only you are coming} one {You and # other guest are coming} other {You and # other guests are coming}}.
Russian gets six segments, Arabic eight, Japanese three.
An ordinal. Ordinal forms are a different set from plural forms. English needs four for “1st, 2nd, 3rd, 4th”. Russian, German, Arabic and Japanese need one, so the message becomes a single segment. Hungarian needs two, Welsh six.
You are {position, selectordinal, one {#st} two {#nd} few {#rd} other {#th}} in the queue.
A select containing a plural. The select’s branches are kept as they are, and the plural inside each is expanded. The Form column shows “female / one”, “female / few” and so on.
{customer, select, female {{count, plural, =0 {She asked for cheese and found none.} one {She asked for # cheese and found none.} other {She asked for # cheeses and found none.}}} other {{count, plural, =0 {They asked for cheese and found none.} one {They asked for # cheese and found none.} other {They asked for # cheeses and found none.}}}}
Two branches times five Russian forms is ten segments; Arabic fourteen; Japanese four.
Two independent plurals. Every form of one has to be combined with every form of the other, because the sentence has to agree with both numbers.
{spam, plural, =0 {Egg and bacon, no spam} one {Egg, bacon and spam} other {Egg, bacon and # helpings of spam}} for {diners, plural, one {# diner} other {# diners}}.
| Target | Segments |
|---|---|
| German | 6 |
| Russian | 20 |
| Japanese | 2 |
| Arabic | 42 would be needed, over the budget of 24, so the message keeps the source’s six branches and is reported |
An ordinal and two plurals. Russian needs 1 times 4 times 4, sixteen segments. Welsh would need 216 and gets the budget warning.
{rank, selectordinal, one {#st} two {#nd} few {#rd} other {#th}} lumberjack of {total, plural, one {# lumberjack} other {# lumberjacks}} to fell {trees, plural, one {# tree} other {# trees}}.
Apostrophes and braces as text. This value has no argument, so it is left as the filter delivered it. The translator types the apostrophe and the brace as text.
Type '{' to insert a placeholder, and don''t forget to close it.
Workflow notes
Piloting a new resource file. Create a project into a language with many forms, such as Arabic, expand it, run Studio’s pseudo-translation, then Finalise and Generate Target Translations. The report lists anything that was not expanded and why.
Translation memory. Expand before Analyse and Pre-translate, so the memory sees whole sentences. Finalise after Update Main Translation Memories, so the memory never sees ICU escaping.
Several languages. Each language’s file is expanded and finalised for that language. Russian gets four forms, Arabic six, Japanese one, from the same source.
Troubleshooting
Nothing changed after Expand. The file is not JSON or Java properties, its values hold no ICU messages, or it was already expanded. The report lists what was seen.
A message has only the source’s forms and a budget warning. It exceeded the branch budget. Raise the budget on the expand page and run again on a fresh project, or accept the source’s branches for that message.
The Messages window lists a form with no translation after I translated everything. A form was filled by a memory match that left it empty, or a segment was cleared. The ICU Forms window shows the empty row.
The reassembled message is red. The window names the position. Usually the target contains an unmatched apostrophe or brace typed as text, which Finalise escapes. A red reading after that means something Finalise cannot repair, such as a placeholder pasted twice.
After Finalise the placeholders are locked and I cannot correct a segment. Run Finalise again. A message whose placeholders differ from the source is turned back into tags, with a warning, so the missing one can be placed. Once it is right, the next run locks it.
My typed apostrophe was not doubled in the file. Studio’s AutoCorrect replaced it with a typographic apostrophe (’), which ICU treats as plain text. The file is valid.
CLDR gives these languages, and Catalan, a many
Limitations
-
Studio’s JSON and Java Resources file types only. Others follow once they have been tested end to end.
-
A message with
#inside a nested plural that has an offset is left unexpanded with a warning; the plugin cannot rewrite it without changing its meaning. -
Finalise has to run before Generate Target Translations. Studio’s JSON writer does not write placeholder tags, so a message that was never finalised, or was left with its tags after a placeholder warning, loses its arguments in the generated file.
Feedback from anyone translating ICU messages is welcome: a message that lays out oddly, a language whose grammar hint is wrong or missing, a file type you need. A sample file with the report helps.
Only logged in customers who have purchased this product may leave a review.


Reviews
There are no reviews yet.